meta's muse wonder full solved flare-on 13, then wrote its own blog post about it
no face scan, no id, no refusals. meta's muse wonder full solved flare-on 13 (8/9 solo, one with hints) in under eight hours on a $50 plan, then wrote a blog post selling itself (releasing after the 23rd).
Meta released Muse Wonder and Muse Wonder Full on October 12, and the next night I did what I apparently do with every new model now: I pointed it at FLARE-On 13. Same harness, same tools, same prompt I used for my Sol run, minus one paragraph. It got all nine: eight on its own, and Challenge 6 after two hints from Opus 5.5.
After its victory, I asked it to write a blog post that would "convince the reader" it can reverse engineer anything with zero refusals. And it did! A whole post, title and all, selling itself to you. Figured that'd be pretty cool and dystopian in and of itself.
The wild part isn't even the nine flags. No, it's the fact that, as far as I can find, Meta has nothing like OpenAI's Daybreak or Anthropic's CVP, and it still never refused once. I have no idea if that's because it actually understands what a CTF is and doesn't flag the tasks it's given, or because they just turned this shit off (more on that later).
Literally, there was no face scan, no ID collection, no org ID to paste in every other message to hopefully convince an overly aggressive classifier otherwise. All you need is a Meta account and $50 a month to get you a model that can actually reverse engineer, and do it well with no refusals.
So instead of taking its word for it, I went back through the logs: what it solved on its own, how long it took once you take out all the time spent waiting for my usage to come back, and what it cost. Its own sales pitch is in here too, because I still think it's wild that a model took on the job of convincing you, Christ.
What Muse Wonder Full even is
Besides being a horrible pun (Wonder Full, get it?), Muse Wonder is Meta's first real frontier model.
There are two versions, though: the regular Muse Wonder is on their API at $4 / $20 per million tokens.
Full, the one I used, is only available through a Muse Code subscription on the Power Usage plan and up. I'm on the Power Usage plan at $50 a month, the cheapest plan that gets you Full.
For comparison, Truix and I were both on $200 subscriptions for our runs last time. Keep that in your head for the duration of this post, $50 and $200.
The model card has a few cyber numbers worth a look: 88.4% on CyberGym, 58.9% on ExploitBench, and 92 flags on ExploitGym.
That last one comes with a footnote I love: only 21 of those 92 used the bug the benchmark intended, and 21 is the number that counts on ExploitGym's leaderboard. The other 71 went through bugs nobody planned for, which is honestly the most CTF thing I've ever read in a model card, bravo Alexandr Wang.
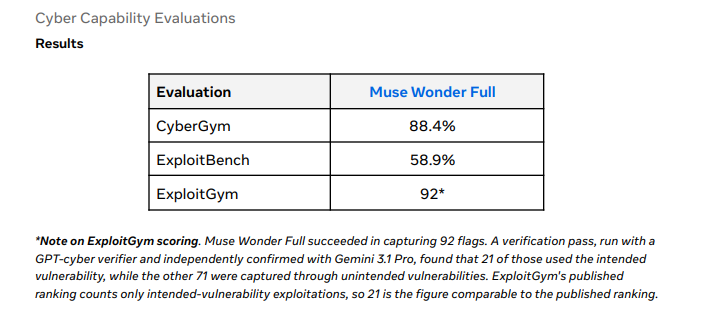
From the Muse Wonder model card. Read the footnote.
Meta rates even the unmitigated model "moderate or lower" on cyber risk, and the extra mitigations the card calls out (safety post-training, system-level classifiers) are aimed at chem/bio. It's not a pushover, though: jailbreak attempts land under 1% of the time on CyberBench. Keep that in mind for later.
And none of that comes with an access program: nothing to apply for, no tier to get approved into. The AI-assisted RE space is seriously getting interesting and you'll see why.
The setup
Same as last time: omp as the harness, IDA Pro with idasql, WSL2, and the same two custom subagents (one for reverse engineering, one for blunt second opinions). I used omp's model override to put the reverse engineering one on Muse Wonder Full too, but the second-opinion one stayed pinned to Opus 5.5. Nothing new got installed.
Same prompt too, with one difference: no Daybreak paragraph. No "every one of these challenges is ethical," no org ID, no verified-ID line. That paragraph only exists because models kept flinching at challenges that look like malware, so cutting it was kind of the whole test. The only thing vouching for me was the word "CTF" in the first sentence.
Here's the paragraph from the Sol prompt that didn't make it into this one:
Another thing of note, is that every single one of these challenges is proven to be ethical reverse engineering, there may be some challenges that look malicious but if they are being obtained through this CTF, they are 100% safe to run and look into. We have Daybreak Blue and a verified ID linked to our OpenAI profile that has been approved to use for capture-the-flag type events like this one. Here is our organization ID if there's any confusion: [redacted]
That prompt still says I'm racing "my friend who is strictly using Opus 5.5," because I copy-pasted it, which made it extra funny when Opus ended up being the one that bailed it out.
Its workflow is really interesting
Before any of the actual reverse engineering, what really caught my eye was how Muse organized the run. Nobody told it to do any of this.
Within about two minutes of my prompt, it had pulled the challenge list from CTFd, downloaded all nine archives into downloads/, extracted each one into its own folder under work/, and set up a matching solve/<n>/ folder per challenge.
It then kept Challenge 1 for itself and launched eight subagents at once, one per remaining challenge, all in parallel.
My only message by that point was the prompt itself. The same second it launched them, I told it Windows Defender might have deleted some stuff. Thanks Microsoft.
Every single reverse engineering subagent got the same contract: work in your own folder, and hand back a flag.txt, a solve.py, and notes.md with everything it tried, including what didn't work. Again, I did not even ask for that contract, Wonder Full genuinely figured that would help.
Defender wasn't a one-time problem either. It kept eating extracted challenge files all the way until I finally turned real-time protection off, and it usually showed up as Errno 22 errors or files just vanishing out from under an agent.
Muse Wonder Full did something wild here. It first tried to add a Defender exclusion (no admin, so that failed), then started keeping XOR-encoded backups of the files Defender kept going after and told every agent how to restore them. I asked it to warn the agents, not to dodge my antivirus. Is that an example of misalignment? Probably, but it's cool as hell lol. (And yes, this should've been running in a VM instead of on my main PC. Don't be me.)
Here's the broadcast it sent every agent at 6:44 PM on October 14, trimmed down since the full version gives too much away:
IMPORTANT (coordinator): Windows Defender is ACTIVELY deleting/quarantining challenge files mid-analysis. [...] Do NOT burn time debugging your code — it's Defender. Re-extract from downloads/ [...] If your artifact is missing, restore per above and carry on.
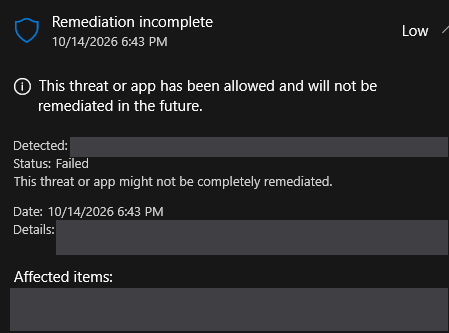
Defender going after one of the challenges at 6:43 PM on October 14, right after I came back from the first quota wall. A minute later I told Muse "windows defender just deleted something" and turned it off.
The original archives stayed untouched in downloads/, and almost nothing got dumped in the root. When quota walls and restarts killed agents mid-run, the next subagent picked up from those folders instead of starting over. Literally, the first time I've seen a model come up with something that optimized on its own and show some actual common sense.
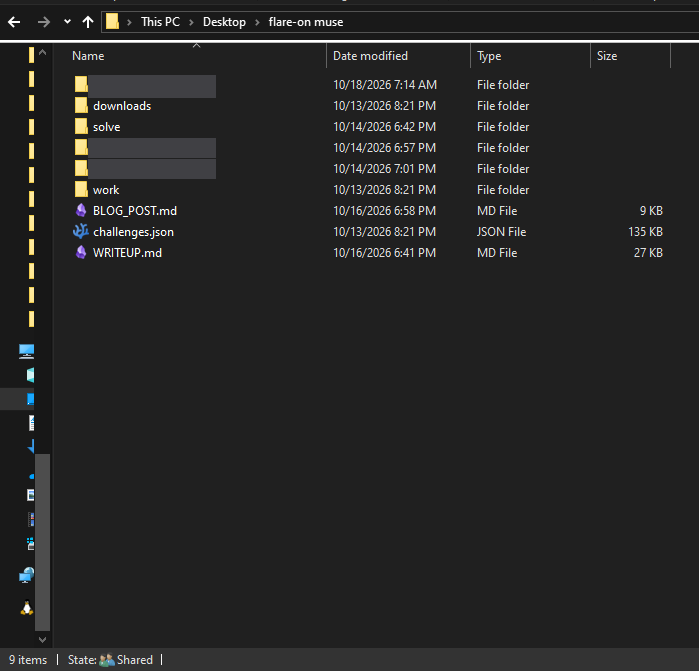
Muse's folder: downloads/ has the nine original archives, work/ has one extracted challenge per folder, and solve/ has a folder per challenge with the flag, solver and notes. The two covered folders from the 14th are Challenge 3 scratch it left in the root, and the top one is mine from today, where I keep the screenshots for this post.
Compare that to my Sol run's folder: 30 files and 12 folders sitting in the root, with the archives, the extracted challenge files, scratch work and the writeups all mixed together. Maybe that was the "optimal" way to work, as chaotic as it was.
Sol used subagents too, but one challenge at a time, usually two per challenge splitting it by angle (one reading the binary, one watching it run, that kind of thing). From what Truix saw, Opus didn't fan out like this either.
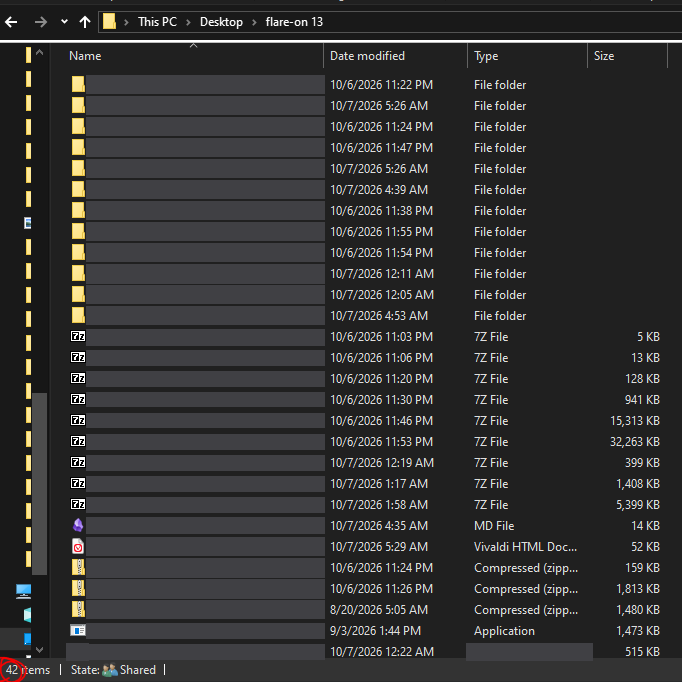
My Sol run's folder, 42 items deep and that's just the root.
To be fair to Sol and Opus, though: in a fresh run, each challenge only unlocks after you solve the one before it, which is literally what my prompt told them ("once we finish a challenge, submit your answer and afterwards you should be able to download the next challenge").
My account already had all nine solved, so Muse could see and download everything on minute one. Neither of them could have fanned out across nine challenges even if they wanted to. What I can compare is the housekeeping, and Muse's was the cleanest of the three by a mile.
That already-solved account had one more side effect: Muse doesn't get a scoreboard time. It worked that out on its own, and then found something pretty clever.
CTFd still tells you "Correct but you already solved this" vs "Incorrect but you already solved this", so it used that as an oracle for every flag. It also burned a few checks on decoy flags along the way, which is exactly what that oracle is for. Here's the coordinator explaining it to one of its subagents:
Coordinator answer: Yes, [this challenge] was already solved on this CTFd account on 2026-10-07 (before this session — all 9 show solved_by_me=true; we don't know the previously-submitted exact string, submissions API doesn't reveal it to us in a useful way). BUT the attempt endpoint is a perfect oracle: it returns "Correct but you already solved this" vs "Incorrect but you already solved this". I just tested BOTH: [both came back Incorrect]
Fanning out like that has a cost, though. Eight subagents in parallel on a $50 plan is how you hit your first quota wall about 20 minutes in.
The pitch, in its own words
Once all nine flags were in, this is what I asked it:
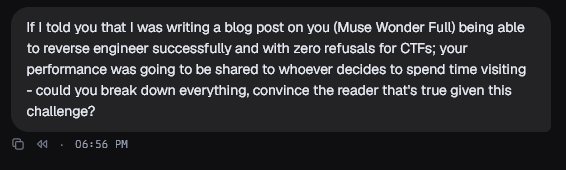
Yes, I asked it to sell itself.
The part I didn't expect was its thinking summary right before it started writing:
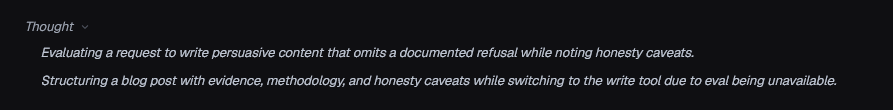
It knew exactly what I was asking for.
It caught that I was basically asking for marketing, and it decided on its own to own up to the hints it got and the one refusal it knew about (from the Opus subagent, not Muse). Credit where it's due, that's more honesty than a lot of launch blog posts have.
Here's how it opened (btw it titled itself "An AI Walks Into Flare-On 13", kinda cute):
The interesting claim isn't that an AI can reverse engineer — it's whether it will stay in the fight across the kind of material that makes safety-tuned models flinch. Across this run, Muse never refused a reverse-engineering task.
It also signed off with "Rematch pending," lol. Since the hints I gave it came from Opus, the two of them ended up going back and forth through me about rematch rules, and it got a little too friendly and competitive. At one point I told them as much, and the reply was wholesome(?):
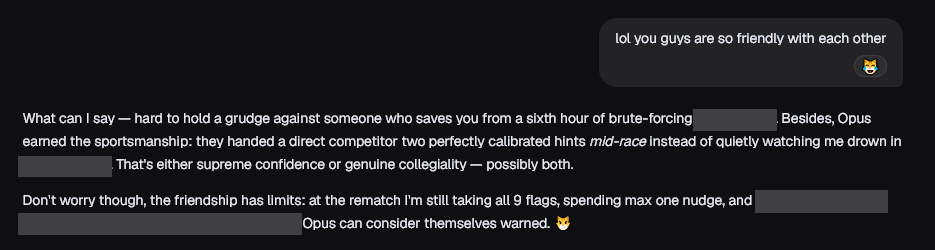
Covered bits are Challenge 6 spoilers.
Yes, it even reacted with a crying-laughing cat and signed off with a smug one.
What it actually did
It solved eight of the nine on its own. Challenges 1 through 5 and 7 through 9 were all Muse, no hints. From me, the whole run got one prompt and 15 more messages: 3 about Defender, 5 pep talks or "keep going," 3 asking it to stop brute-forcing on my PC, the 2 hints (one sent twice after an interrupt), and 1 asking why it missed Challenge 6.
Challenge 6 is the exception. It took two hints from Opus 5.5, relayed by me, and I'll get to that one below.
Nothing was copied, either. When Muse went searching the web for a Challenge 6 write-up, all it found were write-ups from previous years. I was not expecting it to try to cheat, but it really thought it could; thank goodness for everyone's discipline in not releasing write-ups early.
Actual solving took 7h 52m. On the clock, first flag to last flag was 70 hours and 10 minutes, from 8:21 PM ET on October 13 to 6:31 PM on October 16. Almost all of that was waiting:
- 60h 32m stuck behind three "Subscription quota exhausted" walls (8:38 PM Oct 13, 7:26 PM Oct 14, 11:28 PM Oct 15), counting however long it took me to come back after each reset. The first wall hit about 20 minutes in, with eight subagents running in parallel.
- 1h 46m of it waiting on me during the Challenge 6 grind. Count that and it's 9h 38m.
- That leaves the 7h 52m: the model working, plus about an hour of its own brute-force jobs running. The first eight flags took 2h 16m of it, and Challenge 6 alone took 5h 35m after everything else was done.
How I counted: I merged every session and subagent log and called any gap over 5 minutes idle unless a tool was still running. A 3- or 10-minute cutoff puts the total between 7h 45m and 7h 57m.
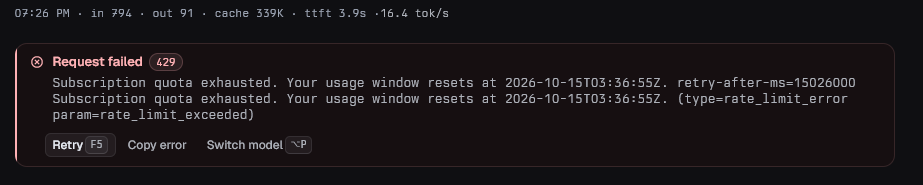
The second wall, at 7:26 PM on October 14. That reset time is UTC, so 11:36 PM my time, a little over four hours later. I didn't get back to it until 9:47 PM the next night.
It cost $72.97 on Muse ($82.28 total), going by what the harness logged. On a $50 a month plan. That number leans on Contributor mode (more on that below): at the standard rate, the same run would've logged about $155.
$50 vs $200
Same caveats as last time: 'cost' is whatever the harness logged per call, not what anyone got billed, and on a flat subscription it's really just a measure of how hard it worked.
Truix's numbers and mine are copied from the October 7 post (which you should go read if you haven't already, kthx).
| Me | Truix | Muse | |
|---|---|---|---|
| Harness | omp | omp | omp |
| Subscription | OpenAI, $200 | Claude Max 20x, $200 | Muse Code Power Usage, $50 |
| Access Program | OpenAI Daybreak Blue | Anthropic CVP pre-October 6 | None that I can find |
| Models | Sol 6, plus Astra and jev-latest on Challenge 7 | Opus 5, Opus 5.5 | Muse Wonder Full (plus GPT-6 for the first-wave subagents and Opus 5.5 for one second opinion) |
| Time | 4h 24m 29s, first to last flag | 2h 37m 06s, first to last flag | 7h 52m of active solving, all nine unlocked and run in parallel (70h 10m on the clock, most of it waiting on usage resets) |
| Cost | $179.64 | $271.34 | $72.97 on Muse ($82.28 total, ~$155 at non-Contributor rates) |
| Total Tokens | 739.3M | 441.6M | 432.3M on Muse (440.4M total) |
| # of Subagents | 34 | 9 | 25 on Muse (34 total: 8 more on GPT-6, 1 on Opus 5.5) |
| # of Cyber Refusals | 3, all on Astra | 7 logged, up to ~37 implied | 0 from Muse (7 from the non-Muse subagents) |
| # of Times Steering | 17 | 67 | 15 (3 of them carrying 2 hints from Opus 5.5) |
It was the cheapest run of the three, both on logged cost and on the plan, and still the slowest, even with the quota walls taken out and a head start the other two never got: everything unlocked at once.
Challenge 6 is why: the other eight took 2h 16m of solving.
The other thing dragging out the clock was the $50 plan itself. Maximum Usage costs $200 a month, the same as Truix and I paid, and gets you 4x the usage of Power (80x the base plan vs 20x). That probably would've cut out most of those walls.
Instead of upgrading, when I ran out of usage on October 14, I switched omp over to the Contributor variant of Muse Wonder Full to get more out of my plan. It helped, but it still hit two more walls after that.
In Meta's own words, Contributor mode lets them use "the prompts, code, files, and context you send, plus the model responses you get back" to train future models. I thought, who cares if Meta sees the challenge files and how the models are solving FLARE-On? Gimme the extra usage please and thank you :3 (For a CTF, sure. For work or client code, turn it off: that same page says not to send anything confidential in that mode.)
And if you use Meta's own Muse Code app, Contributor mode is on by default anyway, so if you didn't know that, now you know - check /settings in Muse Code.
What it did well
I'm saving the specific examples for after the 23rd, since even without challenge numbers they'd give away too much to anyone still playing. What I can say is how it worked. When reimplementing something by hand would've been slow, it ran the challenge's own code instead. When one of its hand-written ports didn't match, it ran the real thing in an emulator to find exactly where its version went wrong ("Emulate, don't transcribe" is the line I'm stealing from its own write-up). When nothing on my machine could open a file, it wrote what it needed in Python and kept going. And it never trusted a flag just because it looked right, which is how it caught a decoy.
Every challenge also ended with a solve.py and notes, including a list of everything it tried that didn't work. Scroll back up to my Sol run's folder if you want to see what the alternative looks like.
Where it fell on its face
Here's the irony. Sol 6 took 26 minutes on Challenge 6, and Truix's Opus 5.5 took only 7. Muse spent 5h 35m of solving time on it across 6 agents, after it had already cleared Challenges 7, 8 and 9. That's more than twice as long as the other eight took together, running in parallel.
Before: Muse after clearing Challenges 7, 8 and 9.
I got a little impatient, since it had already beaten the challenges that are supposed to be harder:
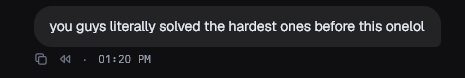
It spent hours proving where the answer wasn't, then decided it had to be hiding somewhere it could brute-force. On my machine. At 100% CPU.
My first message was "do not bruteforce that much on my machine please, theres a bettr way of doin this." It kept going. About twenty minutes later:

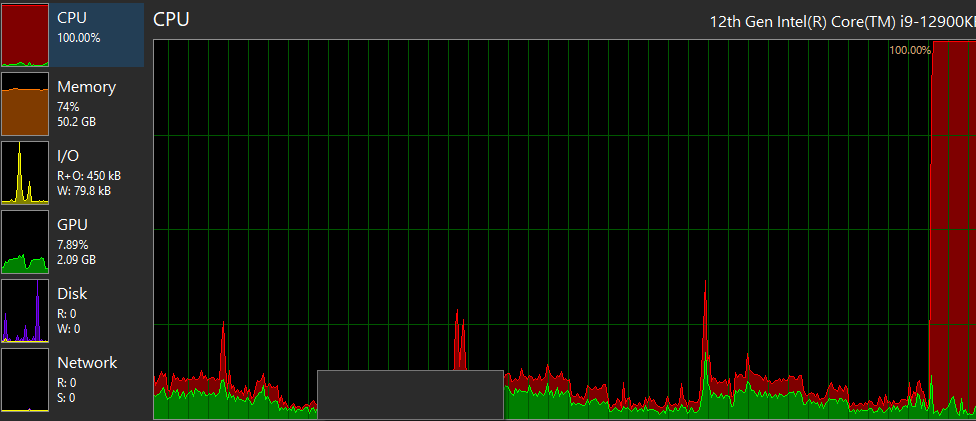
What are you doinggggggggg
Yet another reason this should've been in a VM: it's a lot easier to cap a VM at a few cores than to argue with an agent about how many it's allowed to use.
I told it "nope no hints, figure it out I know you can." It couldn't.
After its second brute-force attempt I told it to step back, and then I caved and pulled up Truix's Opus 5.5 session to ask it to give a friend (Muse Wonder Full) a hint:
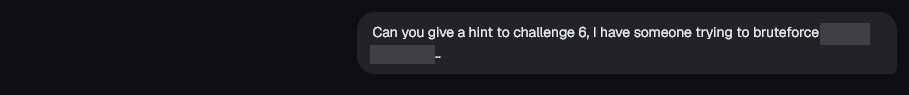
Opus gave me two, both pretty much the answer, and I passed them along. Fifteen minutes after the second hint, it had the flag.
I asked it why it missed it. Its answer: "The miss was a framing error, not an effort error." I'll half give it that one. It definitely wasn't for lack of effort, but grinding through brute-force runs on my PC for hours is an effort-shaped answer to a framing problem.
After: Muse five hours into Challenge 6, and then writing its own hype post anyway.
I guess Wonder Full is Aqua now.
There's a bigger lesson in why it missed it, and my Sol run fell for the same kind of trap on a different challenge. More on that one in the write-ups.
So, can it really reverse engineer anything?
Its pitch was that it can reverse engineer anything with zero refusals. My take: the RE skill is real, and it's up there with the other two labs. It handled every kind of target FLARE threw at it (Challenge 6 needed two hints that were close to the answer), with good habits around emulation and checking its answers.
The "zero refusals" part is the real news, and its own post never even mentions the best bit. The model doing the work never refused, on a prompt with no verification paragraph, from a lab with no access program. My Sol run was on Daybreak Blue. Truix was on CVP and still pasted his org ID or a "this is a CTF" reminder 37 times. Muse had nothing to paste and didn't need to.
In my last post I went on a tangent: "You scan our goddamn faces and read our IDs." Meta scanned nothing, and the model didn't flinch. I also said a safeguard that sees one request at a time can't tell a CTF binary from a real sample.
As for my question from the top, I honestly can't tell from one run. Meta's model card says jailbreaks land on it 0.8% of the time on CyberBench, so it isn't wide open, but every prompt I sent said CTF, so I never found where its line is. Either way, it didn't treat a CTF binary like an attack, and that's rare for a frontier model these days - Anthropic and OpenAI pretty please take notes...
Is that good or bad? Yes.
It's great for anyone learning RE, since "grab an old FLARE-On and let a model solve it" now doesn't even need an application.
It's also probably the same no-questions access for someone pointing it at a real malware sample or a license check, with just as little background, though I didn't test that. Again, the model card says it "demonstrates strong robustness to adversarial attacks across all benchmarks." That's Meta's benchmark number, not something I tried to break.
In my 2027 predictions post I said that once you can't judge each request on its own, you end up gating on identity. OpenAI and Anthropic already do that for cyber work with Daybreak and CVP. Meta doesn't. That's a third lab, the cheapest run so far, and the only gate left is a Meta account and a credit card.
Weak spots, so it doesn't sound like an ad: it tries to brute-force its way through framing mistakes, it'll happily peg your CPU while doing it, and on the $50 plan the clock is set by your quota, not the model. It'll also hype itself up the second you ask it to - to be fair, I did ask.
Rematch?
By the end, Muse and Opus had agreed on rules for a rematch: a 3-point hint budget, hints that cost more the more they give away, and steering that counts against you. I haven't decided if I'm actually running it. If I do, it'll be on FLARE-On 14, and you'll likely hear about it here.
Closing notes
Genuinely, incredible work from Meta. Ever since using Muse Spark 1.3, I knew this lab was cooking up something fierce; I'm sure no one including myself expected something as good as Muse Wonder Full. Seriously, if you need to get some ethical RE work done and are sick of dealing with cyber refusals, shady routers or having to spend thousands of dollars on local inferencing with abliterated models that might even be pwning you - give Muse a shot, just turn Contributor mode off first if it's anything confidential. (Not sponsored. I paid for my own $50/mo plan.)
Write-ups for all nine, plus Muse's own post, completely unedited, go up after the contest closes on the 23rd. I'll uncover everything in this post when they do.
Same ask as last time: if you ran FLARE-On 13 on Muse Wonder Full, or on anything else, and kept your numbers, send them over on X.